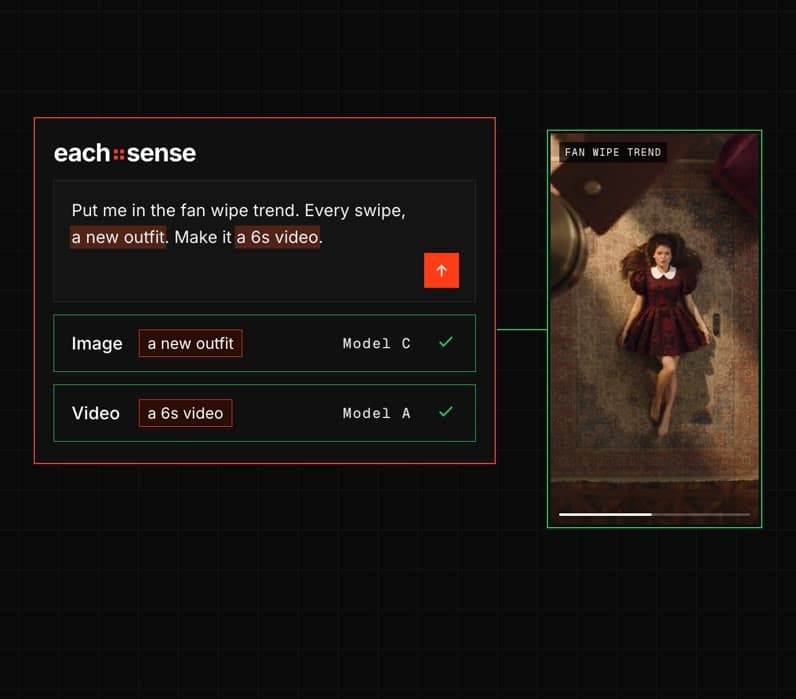
PixelByte: 10 models in the time one deploy used to take.
PixelByte’s CTO ran model deployment, scaling and queue work with a single engineer. With each::labs that infra layer is gone, and the same team ships 10 models in the window a single deploy used to take.
10 models added in the time one deploy used to take.
New models live
Day 0
Ready on launch day. No deploy, no scale test.
Router overhead
<120ms
Per run. The rest is the model doing the work.
The customer
PixelByte builds generative AI apps. One turns a single photo into a video with 200+ effect templates, from pet dances to museum portraits, and another creates art, avatars, logos and album covers. Its CTO and a single engineer used to carry the whole model infrastructure.
The problem
One engineer managed model deployment, scaling and queue mechanics. Maintenance and concurrency issues blocked new model rollouts, and every new model demanded another deploy and another scale test. Engineering hours kept disappearing into infra instead of the product.
How they use each::labs
PixelByte picks from open and closed models for each feature, and each::labs handles hosted inference, concurrency, scaling and queues. New models go live without deploy or scale work, with faster inference and no concurrency blocks under load.
The output
What people make with PixelByte’s apps.
Your petVideo · Pet dance trend
Your selfieVideo · Trend
Your selfieVideo · Cartoon avatar
Image · Album cover
The results
Numbers, before and after.
Models shipped per deploy window
1 → 10
Before
After
Engineers on deploy and scaling
1 → 0
Before
After
Concurrency blocks under load
Frequent → None
Before
After
Customer story
More like a technical partner.
“each::labs lifted the entire deployment burden from us. But what really keeps us is the partnership. A model can always be solved another way; a real partner cannot.”
Furkan SandalCTO at PixelByte
Ready to close the gap?
Bring the idea. Build the workflow. Produce the result.
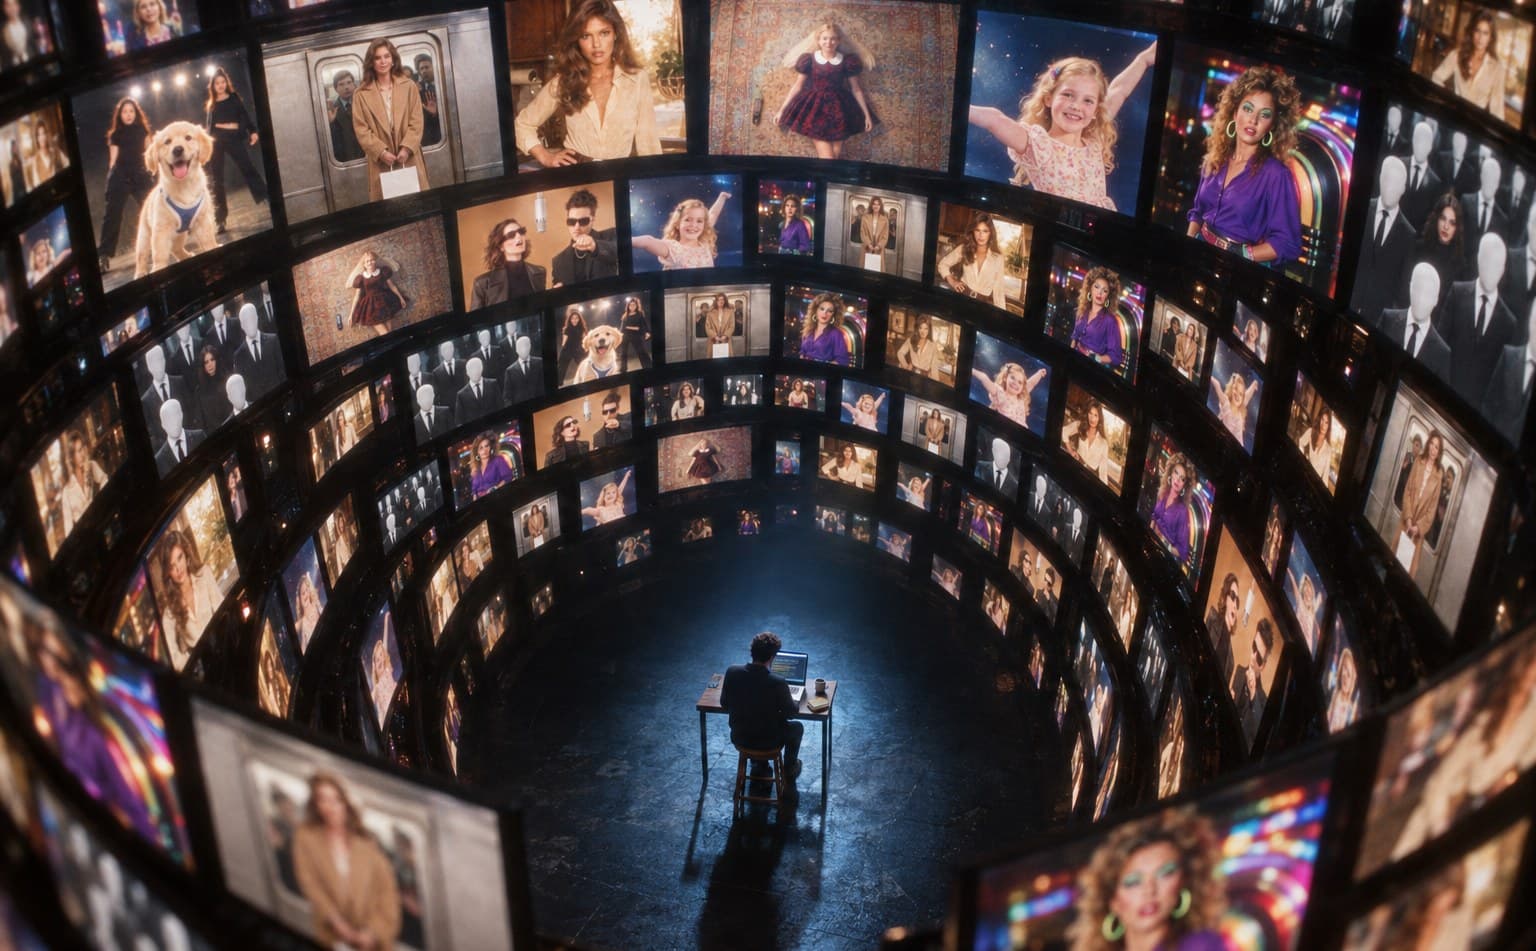
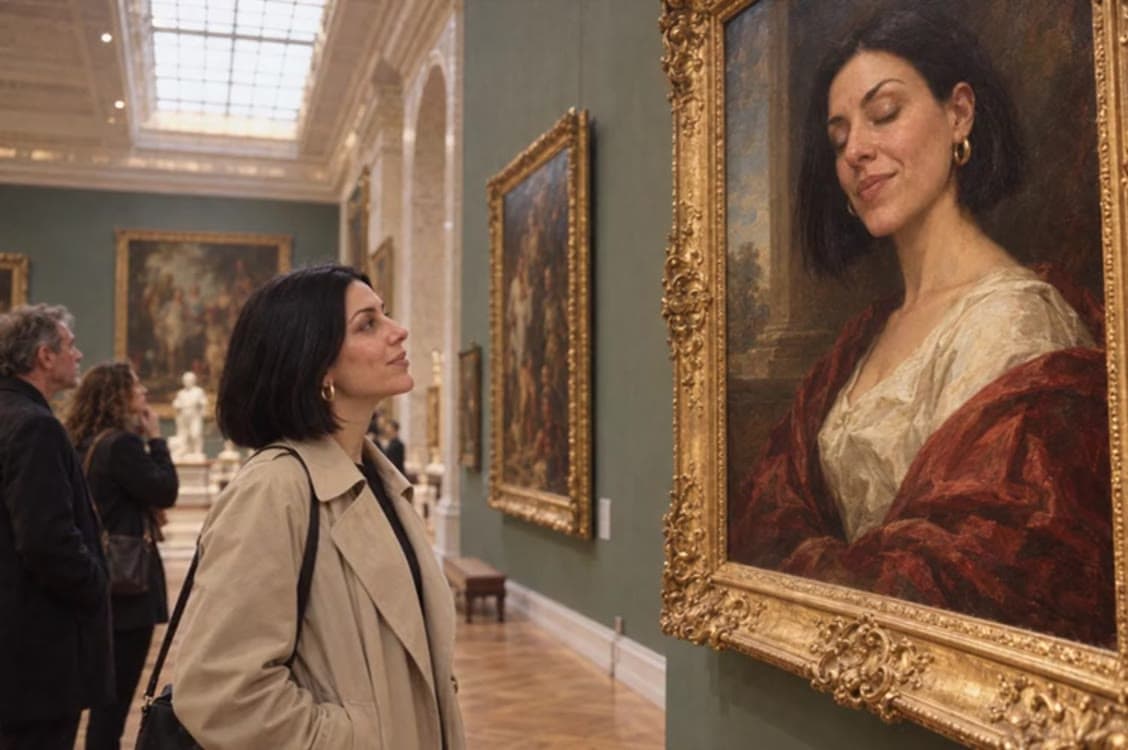
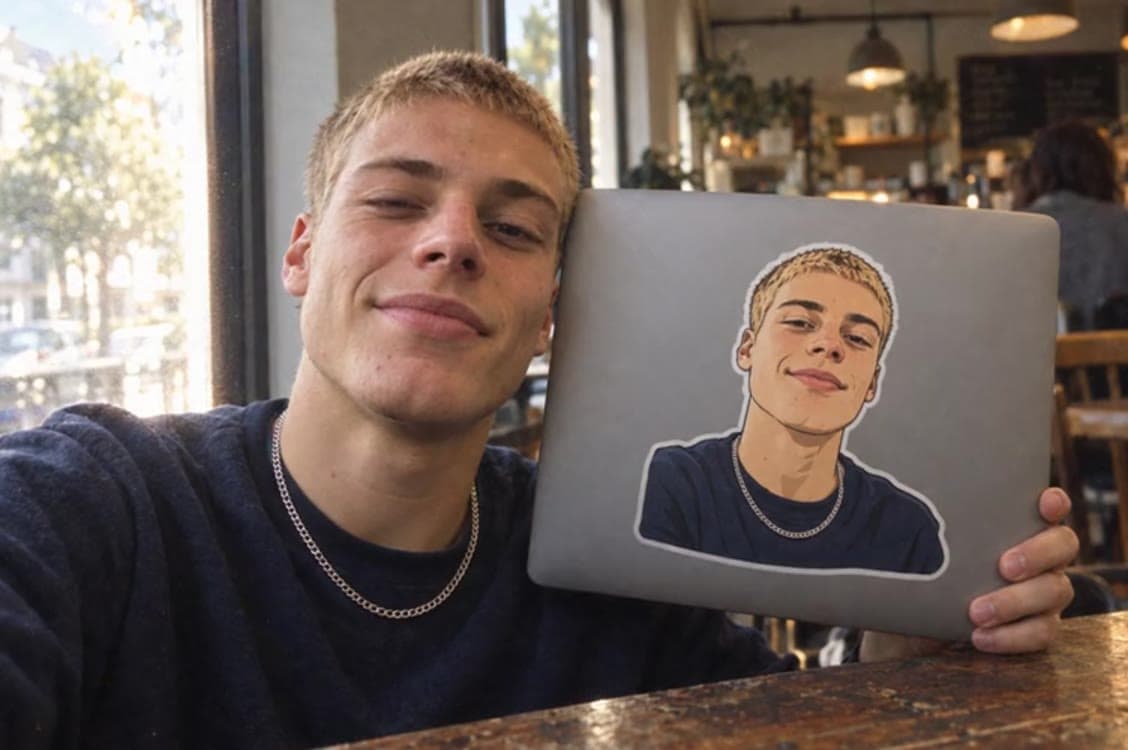
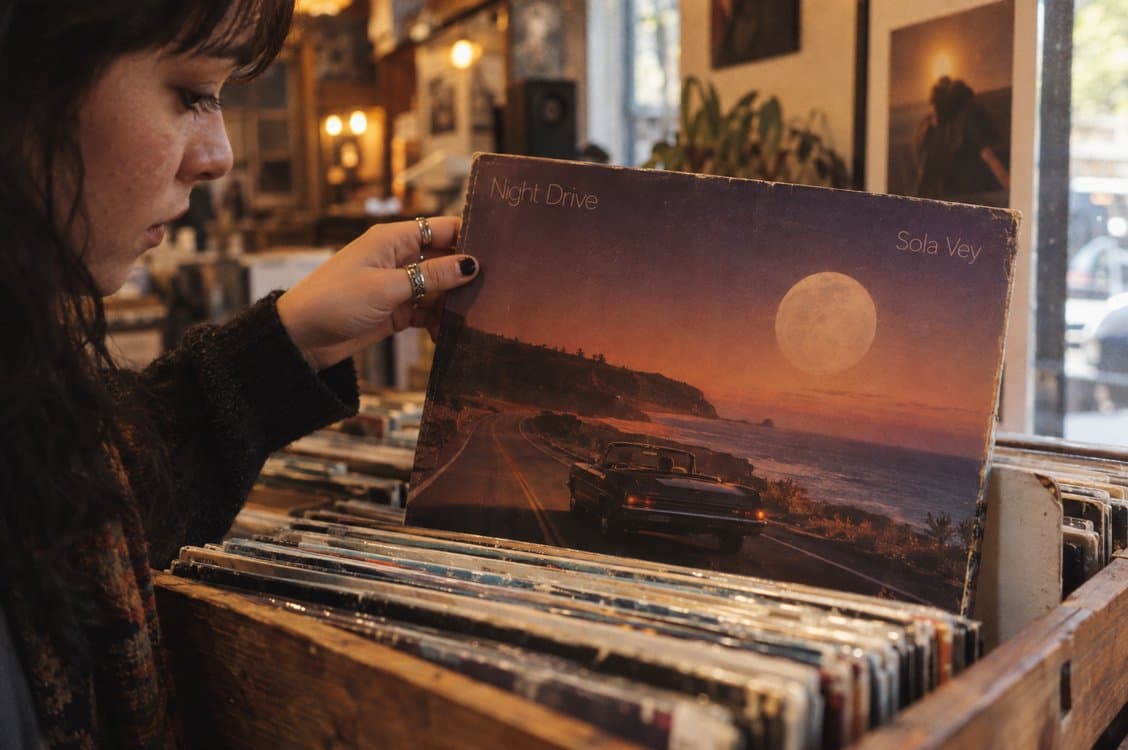 Image · Album cover