Apps and platforms
Turn every trend into a template. Your users add a selfie and star in it while the trend is still trending.
New AI video model by 
Cast anyone. Keep every move.
Lockstep swaps the people in any video for your own characters, from one photo each. Motion, lip sync and camera stay exactly as shot.
Lockstep needs a reference video and one photo of each character. That is the whole brief.
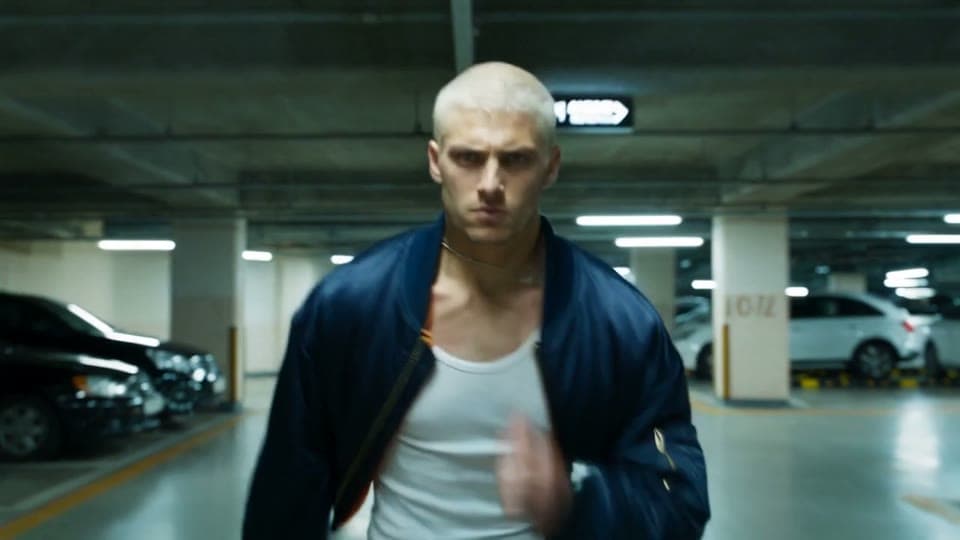
Any clip works: a dance trend, an ad, a stunt or a scene from your film.
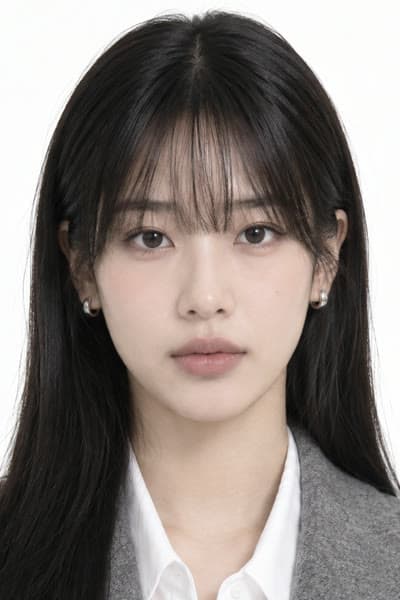 @Image1
One clear photo per character. Tag each one in your prompt as @Image1, @Image2 and so on.
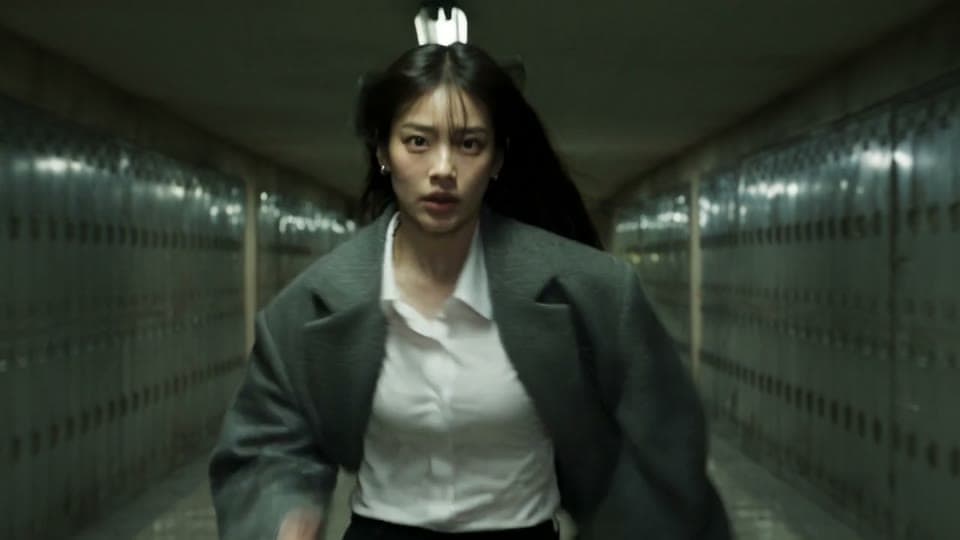
Same length, same timing, same camera. Only what you ask for changes.
Replace the runner with  @Image1. Set the scene in a school hallway.
The new cast hits the same marks as the original take, frame for frame.
Lockstep and two other character swap models got the same video and the same photos. Nothing is retouched, so judge for yourself.
Recast one ad for every market, audience and season. Same counter, same light, same timing, with a new lead in every version.
Five cast photos, one ad. Pick a face to jump to that version.
Face, hair, skin tone and outfit come from your photo and stay the same from the first frame to the last.
Only the characters you tag change. Background, lighting and framing stay as filmed.
Swap one person or a whole group in a single run. Tags keep every character in its place.
Pets, mascots and stylized characters pick up the motion the same way.
Turn every trend into a template. Your users add a selfie and star in it while the trend is still trending.
Shoot a stunt once, then put any actor in it. Same choreography, same camera, no reshoot.
Drop yourself, a friend or a mascot into any scene and keep every beat of the original.
Run Lockstep in the playground, through the API or inside a workflow. Same inputs, same result, at any volume.
Read the API docs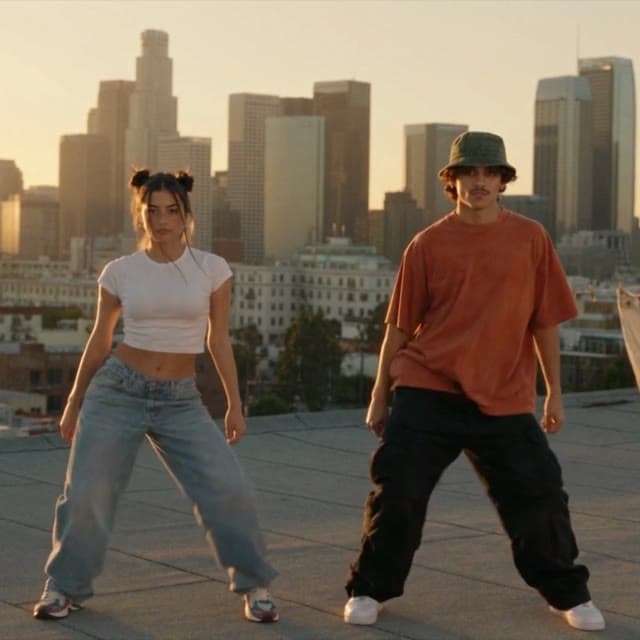
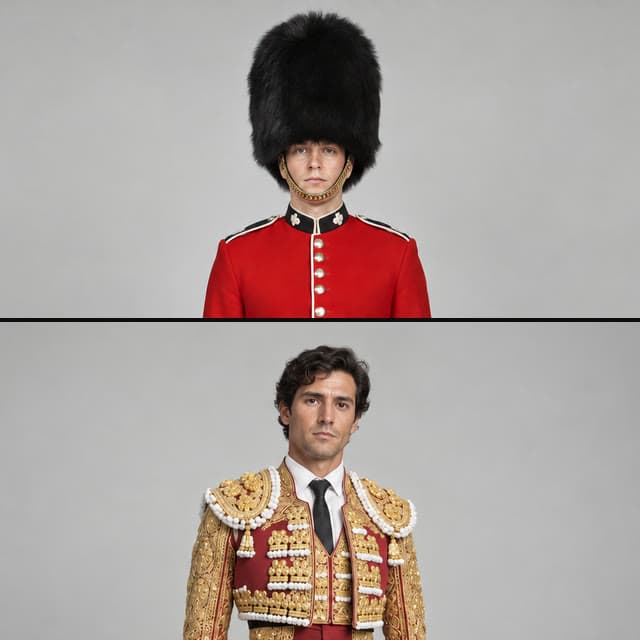
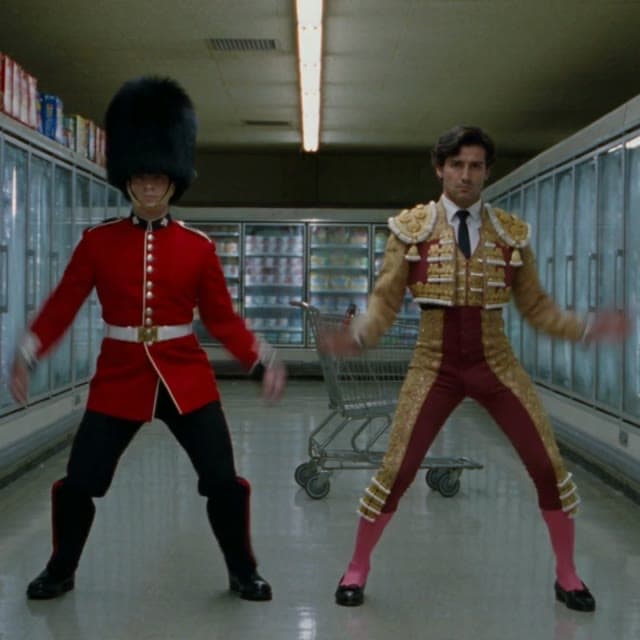
Swap the dancers for  @Image1 and
 @Image2 in a supermarket aisle.
curl -X POST https://api.eachlabs.ai/v1/prediction \
  -H "Authorization: Bearer $EACHLABS_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "lockstep",
    "version": "1.0.0",
    "input": {
      "video_url": "https://your-cdn.com/dance-trend.mp4",
      "image_urls": [
        "https://your-cdn.com/guard.jpg",
        "https://your-cdn.com/matador.jpg"
      ],
      "prompt": "Swap the dancers for @Image1 and @Image2.",
      "resolution": "720p"
    },
    "webhook_url": "https://your-app.com/hooks/lockstep"
  }'
const res = await fetch("https://api.eachlabs.ai/v1/prediction", {
method: "POST",
headers: {
Authorization: `Bearer ${process.env.EACHLABS_API_KEY}`,
"Content-Type": "application/json",
},
body: JSON.stringify({
model: "lockstep",
version: "1.0.0",
input: {
video_url: "https://your-cdn.com/dance-trend.mp4",
image_urls: [
"https://your-cdn.com/guard.jpg",
"https://your-cdn.com/matador.jpg",
],
prompt: "Swap the dancers for @Image1 and @Image2.",
resolution: "720p",
},
webhook_url: "https://your-app.com/hooks/lockstep",
}),
});
const { predictionID } = await res.json();import os, requests
API_KEY = os.environ["EACHLABS_API_KEY"]
res = requests.post(
"https://api.eachlabs.ai/v1/prediction",
headers={"Authorization": f"Bearer {API_KEY}"},
json={
"model": "lockstep",
"version": "1.0.0",
"input": {
"video_url": "https://your-cdn.com/dance-trend.mp4",
"image_urls": [
"https://your-cdn.com/guard.jpg",
"https://your-cdn.com/matador.jpg",
],
"prompt": "Swap the dancers for @Image1 and @Image2.",
"resolution": "720p",
},
"webhook_url": "https://your-app.com/hooks/lockstep",
},
)
prediction_id = res.json()["predictionID"]Send the video, the photos and a prompt. A webhook tells you when the shot is ready.
Chain Lockstep with upscaling, captions or any other model on each::labs.
Every run shows its cost upfront. Pricing stays transparent and predictable at volume.
Every request is screened by content safety checks before it runs.
Anything else? Talk to an engineer.
Lockstep is a video model from each::labs. It replaces the characters in a video with your own, from one photo each, and keeps the original motion, lip sync and camera.
A reference video and one clear photo of each character. Front facing, well lit photos with the whole head in frame work best.
Yes. Tag each character in your prompt as @Image1, @Image2 and so on, and say who replaces whom.
Only if you ask for it. Lockstep keeps the scene as filmed and replaces only the characters you tag, unless your prompt sets a new one.
Yes. The same model runs in the playground, through the each::labs API and inside workflows, with the same inputs everywhere.
Footage and photos you have the rights to use. Every request goes through content safety checks, and requests that fail them are declined.
Pricing is usage based, and every run shows its cost before you start it. Running at high volume? Talk to our team.
Bring the moves. Bring the cast. Lockstep keeps the rest.