Run AI at scale. Without losing sleep over it.
For CTOs and engineering leaders shipping AI in production. We are already handling millions of requests across hundreds of teams, with security and uptime that keep your platform online while you scale.
Run safely. Don’t crash.
The two things every CTO worries about when AI moves to production: a security gap that surfaces in an audit, or a provider outage that takes the whole product down. each::labs is built so neither happens to you.

Won’t crash on a bad provider day
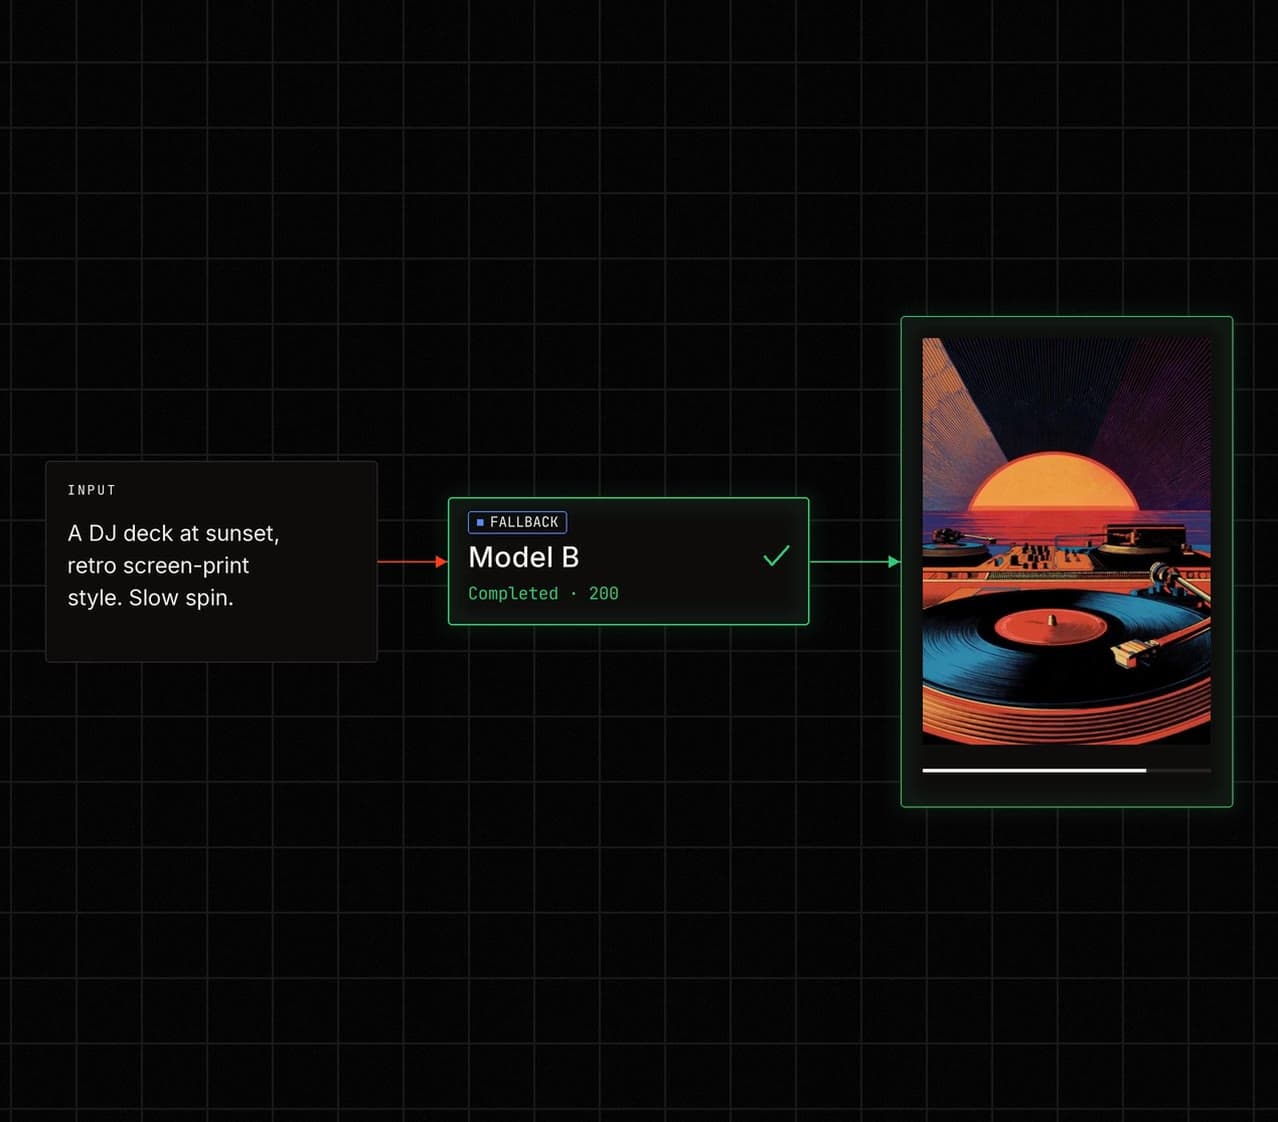
Quality aware failover catches degradations on every call. When a provider fails or slows to a crawl, traffic spills to a healthy fallback in under 120ms, before your users notice.

Won’t leak through a security gap
Your prompts and outputs are stored as execution records in your account, stored files expire on the schedule you set, and we never train models on your traffic. Every provider we route to is listed in our sub-processor register, available on request.

Won’t blow your budget without warning
Per call traces tag every request with cost, latency and the attributes you care about. Finance gets the answer to “who is expensive” without a quarterly instrumentation sprint.
Trusted by teams shipping AI in production



Enterprise features, built around how teams run AI in production.

Team budget management
Set monthly inference budgets per team, per project or per environment, with alert thresholds and hard caps enforced at the router.

24/7 contact with engineering
A direct Slack channel with the engineers who built the router, with on call coverage 24/7/365.

Dedicated customer success manager
A named CSM walks your team through onboarding, traffic design and quarterly business reviews.
Custom volume pricing
Commit to monthly inference volume and the platform fee drops.
No training on your traffic
Execution records stay in your account and stored files expire on the schedule you set. We never train models on your prompts or outputs.

Quarterly business reviews
A scheduled review with your CSM and a senior engineer: cost trends, failover patterns, model swap opportunities and what ships next.
Hands-on technical support, 24/7.
“We work with each::labs on selected products where flexibility, speed, and stability matter most. Their 24/7 support during critical moments has been especially valuable, knowing that there is always a responsive and technically capable team available gives us operational confidence while scaling.”

Aziz GündoğduScate
Procurement docs, one email away.
We don’t hide the paperwork behind a sales call. Email the engineering team and your security or legal counterpart gets a direct reply, usually the same business day.
Security review
Architecture, retention and sub-processors in one document.
Sub-processor list
Current providers and their role, updated as we add models.
DPA
GDPR Article 28 template that we counter-sign.
Custom MSA
Standard template, redlines welcome, handled by engineering.
Uptime and incident process
How we run on call, what counts as a P1 and how we report it.
Pricing terms
Volume commitments, platform fee tiers and payment terms.
Frequently asked questions
The short answers. For anything specific to your pipeline, ask the people who build the platform.
 Talk with an engineerFind your next pipeline opportunity.
each::labs runs at 99.99% effective uptime across the routed path. Because quality-aware failover reroutes around any single provider’s outage in under 120ms, your app’s uptime doesn’t depend on one provider staying healthy. Specific SLA terms are set in the Enterprise contract.
each::labs provides a security review document covering architecture, data retention, and sub-processors (shared under NDA), a current sub-processor list, a GDPR Article 28 Data Processing Agreement that each::labs counter-signs, and a custom MSA open to redlines. Procurement docs are one email to engineering away, with no gating sales call.
Execution records stay in your account and stored files expire on the schedule you set, 180 days by default. We never train models on your prompts or outputs. Provider-side retention follows each provider’s published terms, listed in our sub-processor register, available on request.
Yes. Every Enterprise customer gets a named customer success manager, a direct Slack channel with the engineers who built the platform, and 24/7/365 on-call coverage. P1 incidents are acknowledged the same business day, and a written root-cause analysis lands in your inbox within 24 hours, not first-line ticket triage.
Yes. Enterprise accounts can set monthly inference budgets per team, project, or environment, with alert thresholds and hard caps enforced directly at the router. Every call is traced with its cost, so finance can break spend down by any attribute, with no quarterly instrumentation sprint required.
Use the Contact Sales page or email the engineering team directly. Procurement documents, including the security review, DPA, sub-processor list, and MSA, are available on request without a gating sales call, usually with a same-business-day reply from a security or engineering counterpart.